How recommendation systems work: a guide for leaders

Recommendation systems are big business, and they’re one of my favorite things to build. I’ve designed systems that have shown billions of recommendations to tens of millions of people. They get less attention than they deserve.
Two of the best-known examples come from Netflix and Amazon. In 2009, Netflix paid $1 million to the team that made its recommendations 10% more accurate in the Netflix Prize. Amazon’s 2003 paper on item-to-item collaborative filtering was later picked by the editors of IEEE Internet Computing as the paper that best stood the test of time.
This post explains what goes into a recommendation system and the problems you’ll run into when you build one.
The data a recommendation system uses
Most recommendation systems use three kinds of data:
- Interactions: which customer bought, watched or clicked on which product.
- Customer details: what you know about each customer.
- Product details: what you know about each product, like price, color and size.
The interaction data can be very simple. Here’s a small example, with customers in rows and products in columns. A 1 means the customer bought the product.
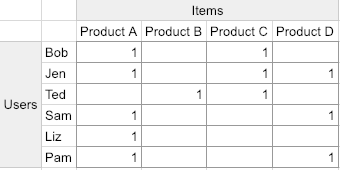
Notice there’s no rating, only whether the customer bought it. That’s often all you have, and it’s enough to make good recommendations.
Collaborative filtering: people like you also bought
With enough interaction data, you can say things like, “Customers like Bob also bought product D.” Look at Jen. She bought the same products as Bob, plus product D, so product D is a good recommendation for Bob. That idea is called collaborative filtering. It’s collaborative because every customer’s history helps make recommendations for everyone else.
The cold start problem
Collaborative filtering breaks down in two places.
A new customer. Say Jim signs up today. He hasn’t bought anything, so he has nothing in common with anyone. This is where customer details help. If Jim’s onboarding answers look a lot like Bob’s, you can show Jim what you’d show Bob. Once Jim starts buying, you don’t need the stand-in.
A new product. Say you add product E. Nobody has bought it, so collaborative filtering never recommends it. Product details solve this one. If product E has the same price, color and size as product C, you can recommend E wherever you’d recommend C until it builds up its own history.
Some models use all three kinds of data at once, which handles new customers and new products from the start.
Recommending things that are hard to describe
Some products don’t fit a neat list of attributes. In 2019, our team built a travel recommendation app from written descriptions of nearly 10,000 places. One of our engineers loves Venice for its art, but not its crowds. When he searched for Venice and picked the tags for painting and art, his top suggestion was Sarajevo. That’s the kind of recommendation people remember, because they’d never have found it on their own.
When a more accurate model isn’t worth running
Netflix never put the winning Netflix Prize algorithm into production. According to Netflix, the extra accuracy “did not seem to justify the engineering effort needed” to run it, as Techdirt reported in 2012. The lesson holds for any AI project. A model only pays off once it’s running in production and improving a metric the business cares about. I cover that step in putting AI into production.
A few other things decide whether recommendations work in practice:
- Popularity bias. If you start by recommending best sellers, your data fills up with best sellers. I explain how to get past that in how popularity bias undermines personalization.
- Ratings. If you use reviews to order what you show, a product with two good reviews shouldn’t outrank one with hundreds. Here’s how to rank products by rating.
- Testing. Every new model should prove itself against the old one with real customers. Multi-armed bandit testing gets you the answer with less wasted traffic.
Recommendations also need a clear view of what customers are worth over time. For a Fortune 250 consumer goods company, we built and run an analytics platform for seven brands with lifecycle views of lifetime value, acquisition cost and retention.
Talk to us
If you’re thinking about recommendations for your products, the first call with one of our senior engineers is free and takes 30 minutes.