Putting AI into production: a guide for business leaders

Building a model is the part of an AI project people picture. The value comes later, when the model runs inside your systems and people act on its answers every day. That step is called deployment, and it’s where a lot of projects stall. It’s one of the five reasons AI projects fail to pay off.
I first wrote this as a five-part series in 2020. This is the whole series in one place, updated for the way we build AI today.
What a model actually is
A model sounds mysterious. It isn’t. Here’s a simple one that predicts the price of a home from its size, using Seattle home sales.

The red line is the model. Written out, it says:
Price = $136 × square footage + $200,000
That’s all it is: two values, $136 and $200,000, plus the instruction for using them. It isn’t very accurate, as you can see from how far the dots sit from the line, but it is a real model. Give it any square footage and it returns a price.
Bigger models work the same way. They have more inputs and many more values, and the language models behind today’s AI assistants have billions of them. They still take inputs and return an answer.
This matters for one practical reason. To put a model into production, your engineers need to store those values and run that calculation every time someone needs an answer. Once they see it that way, the conversation between your AI team and your engineering team gets much easier.
Settle these questions before you build
Say you’re building a website that tells homeowners what their house is worth. The team building the model and the team running the website need to agree on a few things before anyone builds the model:
- How fast does an answer need to come back?
- What goes in and what comes out? Will size always be the only input?
- What should happen when the model is likely to be wrong, for example in neighborhoods where it has missed badly before?
- How will we judge it once it’s live?
- Which of its answers can go straight to a customer, and which need a person to approve them first?
These answers shape how the model is built. When they come up halfway through a project, teams often find the data they need isn’t available, and it can be easier to start over.
Decide between instant answers and scheduled batches
A model can return its answers in two ways.
Instant answers are calculated each time someone asks. A product recommendation on a web page works this way, because the shopper is waiting and their behavior changes by the minute. This works best for fast models.
Scheduled batches are calculated ahead of time and stored. Say you’re sending ten million personalized emails at 6 a.m. It’s much easier to prepare all of them overnight than to call a model ten million times at once. Batches also work well for a sales team that needs a ranked list of prospects every morning.
Each choice needs different data at different times, so make it early.
Measure it twice: before launch and after
Before launch, a model is tested on data it hasn’t seen. If you have 100,000 past home sales, you might build the model on 70,000 and check its predictions against the real prices of the other 30,000. That tells you how accurate it is.
After launch, the business judges the model by the metric the project was meant to improve, such as how many visitors come back to the site or how many customers stay. A model that’s more accurate in testing usually does better in real use, but that’s an assumption until you check it.
The way to check it is a test in production: one group of customers gets the new model, a similar group doesn’t, and you compare the results. I explain how in better testing equals more revenue.
Keep it working after launch
Models get worse over time. Customers change, seasons change, products go out of stock, and the patterns a model learned stop matching what’s happening. A model left alone will drift.
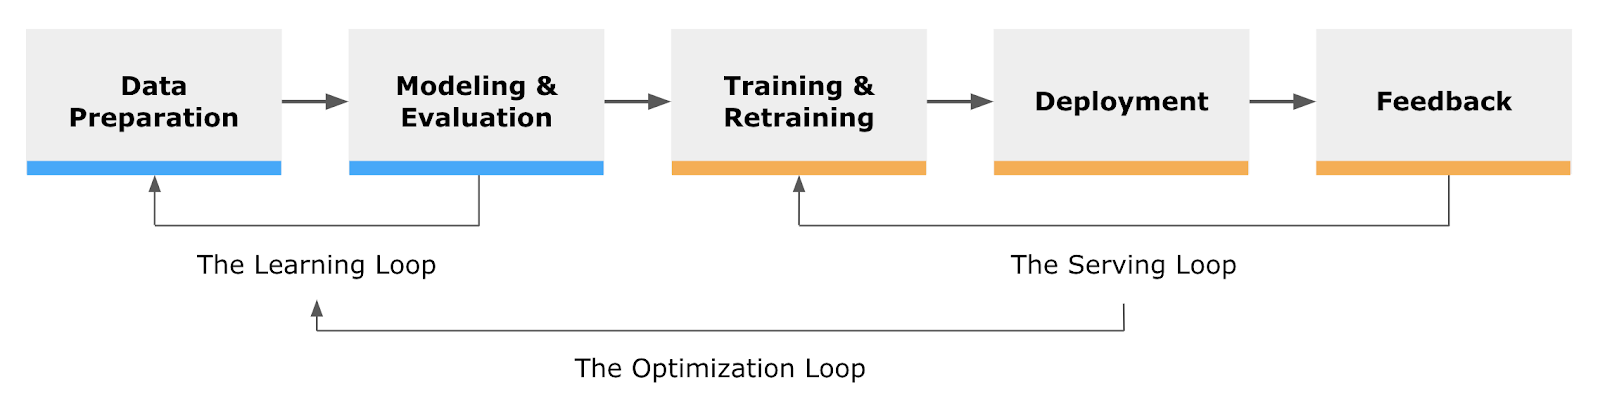
After launch, two of these loops keep it accurate. The serving loop retrains the model on fresh data every day, week or month. The optimization loop goes further: it takes what you learned from live results and uses it to build better models. The optimization loop is where most of the real gains come from.
That’s why I always recommend keeping the people who built a model involved after it goes live. I wrote more about this in models need ongoing maintenance. At Irth, we have run more than 70 models in production since 2020, and we still operate them. You can read about them in the damage-risk models we built for Irth.
A checklist before you start
- Agree on the metric you want to improve and where it stands today.
- Name the team that will use the results, and agree with them on inputs, outputs and speed.
- Choose instant answers or scheduled batches.
- Set the accuracy a model must reach before it goes live.
- Decide which actions need a person’s approval.
- Decide how you’ll measure the live result, and plan the tests that will improve it.
How we do this today
Every AI system we put into production runs on Bennett ONE. It handles the last three items on that checklist on every project. It connects to the data you already have, checks every answer against criteria we set with your team, sends any consequential action to a person on your team for approval, and records every step with its source. The AI model handles one step out of six, the recommendation, and we can change the model without rebuilding anything else. You can see all six in how Bennett ONE works.
Talk to us
If you have a model that works in testing and hasn’t made it into daily use, the first call with one of our senior engineers is free and takes 30 minutes.