Multi-armed bandit testing: A/B tests that waste less

Testing is how you know a change actually worked. A new model, a new page or a new email only counts as better once you’ve measured it against what you had before. The companies that do this well run tests all the time.
It’s also easy to waste a lot of time and traffic on testing. I first wrote about this in 2019, and the method I recommended then is still the one I’d start with: the multi-armed bandit. This post explains how a standard A/B test works, what it costs you, and how a bandit test gets to the same answer with far less waste.
How a standard A/B test works
Say you sell bicycles and you’ve built a new landing page. Your team likes the design but can’t agree on the headline. Version A says “Bike to Work.” Version B says “Win the Race.”
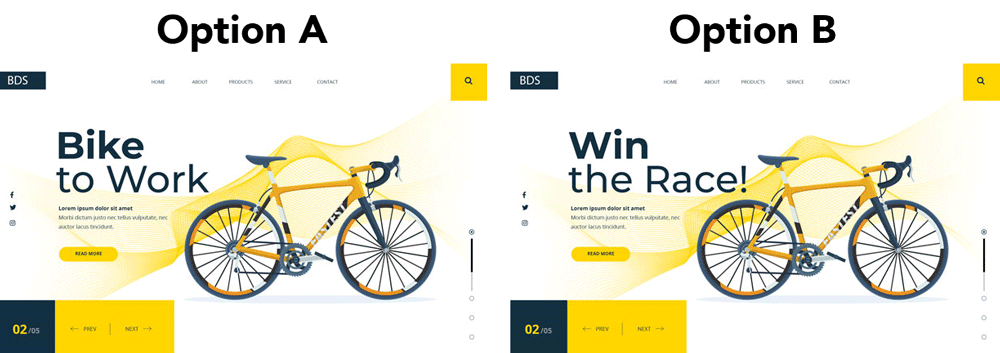
In a standard A/B test, you show version A to one group of visitors and version B to another. Before you start, a sample size calculator tells you how many visitors each version needs. For this test, it said 1,600 each, so 3,200 visitors in total.
You also can’t stop early. If you check the results halfway through and end the test because one version looks like it’s winning, the result isn’t valid. Evan Miller explains why in How Not To Run an A/B Test: if you “regularly check ongoing experiments for significant results,” you’re likely to fall prey to “repeated significance testing errors.”
What a standard test costs you
I ran this test in a simulation 1,000 times. I assumed each visit cost $1.00, that 45% of visitors would click version A, and that 10% would click version B. Our imaginary visitors mostly commute by bike, so the racing headline doesn’t speak to them.
The standard test used all 3,200 visits. Version A got 720 clicks and version B got 160. If we’d shown version A to everyone, we would have gotten 1,440 clicks. The test cost us 560 clicks.
That gap has a name: regret. It’s the difference between the best result you could have had and the result you got. With two options it’s painful. With four or five options, a standard test can need so many visitors that it runs for a very long time, and every visit to a weak option costs you money.
How a multi-armed bandit works
The name comes from slot machines, which are sometimes called one-armed bandits. Picture a room full of them. Each pays out at a different rate, and you have a bucket of coins. You want to win as much as possible.
You’d try each machine for a while to see which one seems to pay best. Then you’d play that one most of the time, while still trying the others now and then in case you guessed wrong. Statisticians call this the trade-off between exploring and exploiting. A multi-armed bandit test handles that trade-off for you. As soon as one version starts winning, it shows that version more often.
There are several ways to run a bandit. I compared four of them in 2019: random selection, epsilon-greedy, Thompson sampling and upper confidence bound. Thompson sampling had the lowest regret in my tests, and it’s the one I use by default.
The same test with a bandit
I ran the bicycle test 1,000 times again, this time with a Thompson sampling bandit. Here’s what happened:
- The bandit picked the right winner 99.4% of the time.
- It needed about 55 visits, on average, to find the winner.
- On average, it showed version A about 47 times and version B about eight times before settling.
- The average regret was four clicks.
The standard test cost us 560 clicks. The bandit cost us four.
When a bandit is the wrong tool
Bandits aren’t the answer to every test. I’d use a standard A/B test when:
- Your audience changes in the middle of the test. If you switch your marketing from commuters to racers halfway through, the bandit’s early learning no longer applies. Stop and start again with the new audience.
- You need to know why a version won. A bandit finds the winner fast, but it gives you less evidence about the reasons.
- The click isn’t what you care about. A version can win on clicks and still bring in customers who spend less over time. If you care about lifetime value, test against that metric, even though it takes longer.
Test every model you put live
The same idea applies to AI. A model that tests well on past data still has to prove itself against what you had before, with real customers. I go through that step in putting AI into production, and skipping it is one of the five reasons AI projects fail to pay off.
Testing matters most for the systems that decide what each customer sees, like product recommendations and personalized offers. On every system we put into production, Bennett ONE records each result and reports it against the value it started from, as shown in how Bennett ONE measures value, so you can see what each change was worth.
Talk to us
If you’re running tests that take months to finish, the first call with one of our senior engineers is free and takes 30 minutes.